

Introduction
Curio is a framework for urban visual analytics: you load city data, prepare it with code, and turn it into linked charts and maps, all on one canvas in your browser. Its building block is the dataflow, a graph of small steps that you can read, rerun and share. This page explains the main ideas and points you to the rest of the guide.
Dataflows and nodes
A dataflow is a set of nodes joined by connections. Each node does one step: it takes what the nodes connected to its input produced, runs, and passes its own result on. Results travel as tables (pandas DataFrames, or GeoDataFrames with geometry), single values, lists, JSON or rasters.
Nodes work at different levels. Some hold Python or JavaScript code, some hold a declarative grammar such as a Vega-Lite chart spec, and some offer widgets, so people with different skills can build one analysis together. Pressing a node's play button runs it, after first running whatever it depends on that is out of date.
Curio also keeps the dataflow's history as you work, and View > Provenance lists its earlier versions in a drawer, so you can step back through them (see Provenance).
The kinds of nodes
The rail on the left of the canvas holds the built-in nodes, in three groups:
- Data and flow. Data Loading brings data in, Data Export saves a result as a file, Data Summary describes a table (its shape, column types and missing values), Spatial Join pairs the rows of two inputs whose shapes meet, Map Editor adds, changes and removes the features of a map's layers, on the map, Data Pool shows a result as a table and marks the rows the views linked to it select, and Note explains a part of the dataflow in a title and a short text.
- Computation. Python Computation and JS Computation filter and reshape data or run your own analysis code.
- Visualization. Vega-Lite draws charts, and maps from a GeoDataFrame; Autark draws 2D and 3D maps and runs GPU computations from one spec; Simple View shows a table, or a card per row for images.
A node can take several inputs: each connection gets its own input circle, and the code reads each input by its name, input_0, input_1 and so on, or through a chip (see Connecting nodes).
A selection in one chart or map highlights the matching rows in the views linked to it, and node code can read it (see Linked views). More nodes come as packages from the Node Catalog, and you can write your own. AI agents attach to a node, a connection or the whole dataflow to help you write code, debug and plan (see AI agents).
The hosted instance or your own computer
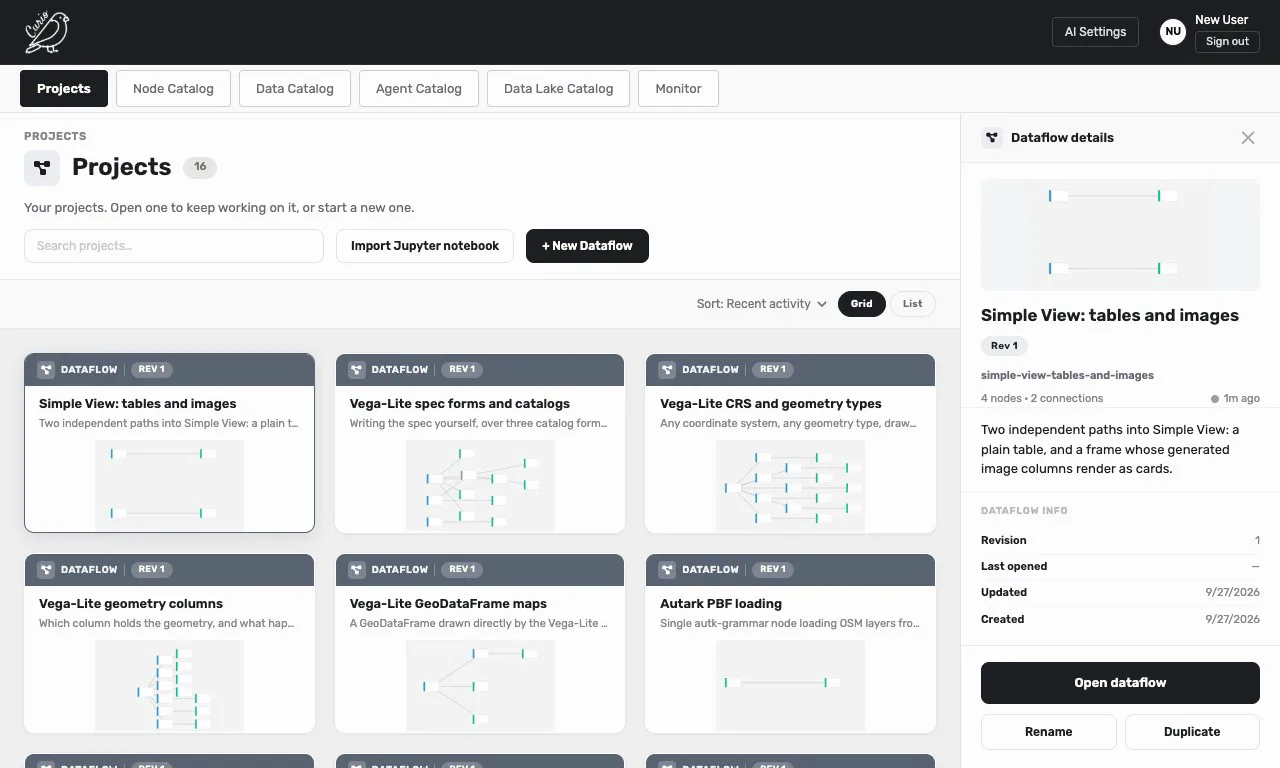
The hosted instance runs in your browser with nothing to install. It has accounts: sign in to save your work, and each new account starts with its own copies of the example dataflows. You can also continue as a guest to look around, without saving.
Running Curio yourself, with pip or Docker, puts its three parts on your computer: a backend that stores your projects, a sandbox that runs node code, and the web app. A local Curio signs you in automatically and can read files from your own disk. To host Curio for a group, with accounts, see Run your own server.
Where to go next
- Quick start: build a first dataflow in the hosted instance.
- Install: run Curio on your own computer.
- Dataflows and nodes and Projects and files: the canvas, running nodes, saving, and notebooks.
- Data Catalog and Discovery Catalog: datasets, your own files, open data portals, storage and services.
- Model Catalog: trained models your nodes run.
- Charts and maps and Dashboards and sharing: views, and pages that present them.
- Run your own server: host Curio for a group, with accounts.